A study found that language-adapted systems sharply reduced the gap, suggesting model choice matters for students using AI in Uzbek.
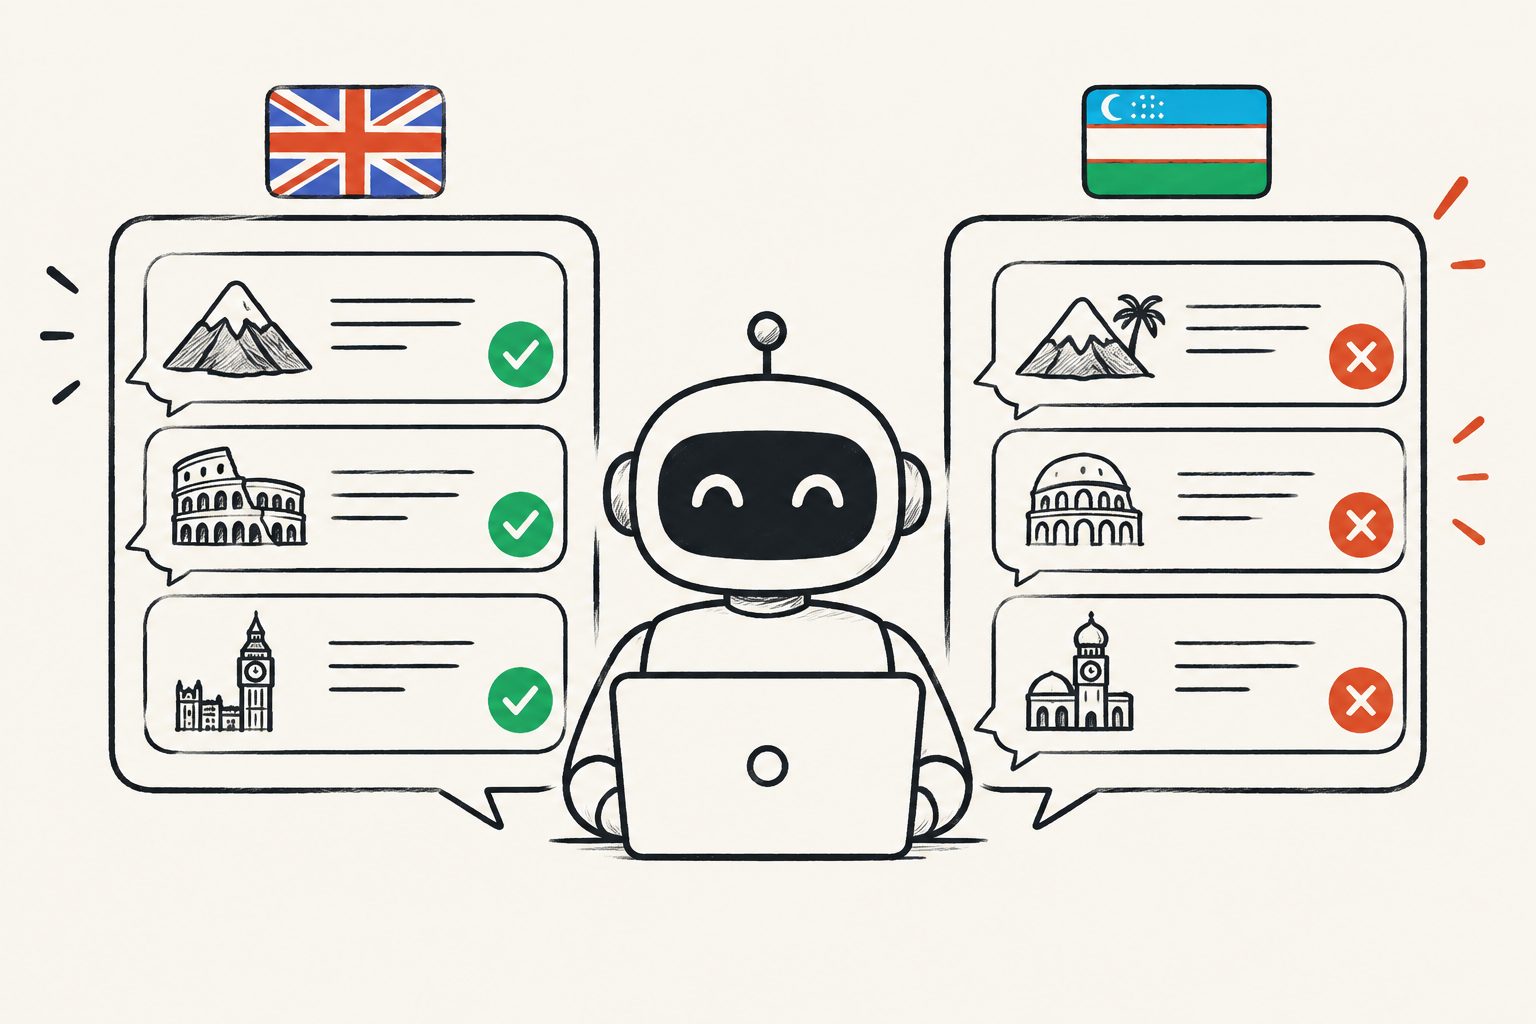
Researchers asked eight open-weight AI language models 100 verifiable factual questions in English, Russian and Uzbek. The pooled error rate was 3.5% in English, 10.9% in Russian and 15.9% in Uzbek, with the difference statistically significant.
The size of the gap varied by model. One 12-billion-parameter general-purpose model performed reliably across all three languages, while smaller models had Uzbek error rates of 24% to 27%. Models that had been further trained or fine-tuned for Uzbek reduced their error rates to 2% to 8%.
What the models got wrong
The study measured factual errors using a fixed answer key. Across all models, the error rate rose from 3.5% for English questions to 10.9% for Russian and 15.9% for Uzbek. The difference was present in nearly every model, although its size varied.
The smaller 1-billion- to 4-billion-parameter models made errors in Uzbek 24% to 27% of the time. A 12-billion-parameter general-purpose model was reliable across the three languages. Models adapted for Uzbek had Uzbek error rates of 2% to 8%, close to their reliability in English.
Why language choice matters
Students using an off-the-shelf AI language model in Uzbek may be several times more likely to receive an incorrect fact than students using the same kind of tool in English. If unverified answers enter student assignments or other academic work, this creates a concern for academic integrity and for equal access to reliable study support.
The results also indicate that the risk is not inherent to Uzbek. Choosing models adapted for the language, and checking reliability separately for each language before classroom use, substantially reduced the measured gap.
Evidence and limits
This was a controlled, reproducible evaluation of eight open-weight AI language models answering 100 verifiable factual questions in three languages. Responses were scored deterministically against an answer key, and the researchers released the questions, code and model outputs for replication.
The evaluation measures factual accuracy on this question set, not learning outcomes or every kind of classroom use. It covered eight models and 100 questions, so the results may not represent all AI systems, subjects or prompts. The abstract also does not describe how the questions were distributed across topics or how well the findings generalize beyond this evaluation.
// Source
Frontiers in Education · 2026 · DOI: 10.3389/feduc.2026.1929327
Authors: Bekhzod Olimov, Botirjon Axmedov, Bakhtiyorjon Kh. Omonov, Begmatov Azizbek Tursunbayevich, Dildora Sherqo'ziyevna Aliyeva, Usmonkhuja T. Tursunkhujaev, Алишер Абдупаттоевич Пармонов, Gʻopporova Nigoraxon Moʻminjon qizi, Vazira Q. Abdullayeva, Xalilova Nilufarxon Bahromovna
Institutions: Kokand University, Kokand University Andijan branch