A study finds that many electronic-structure datasets contain overlapping information, allowing smaller training sets in tests.
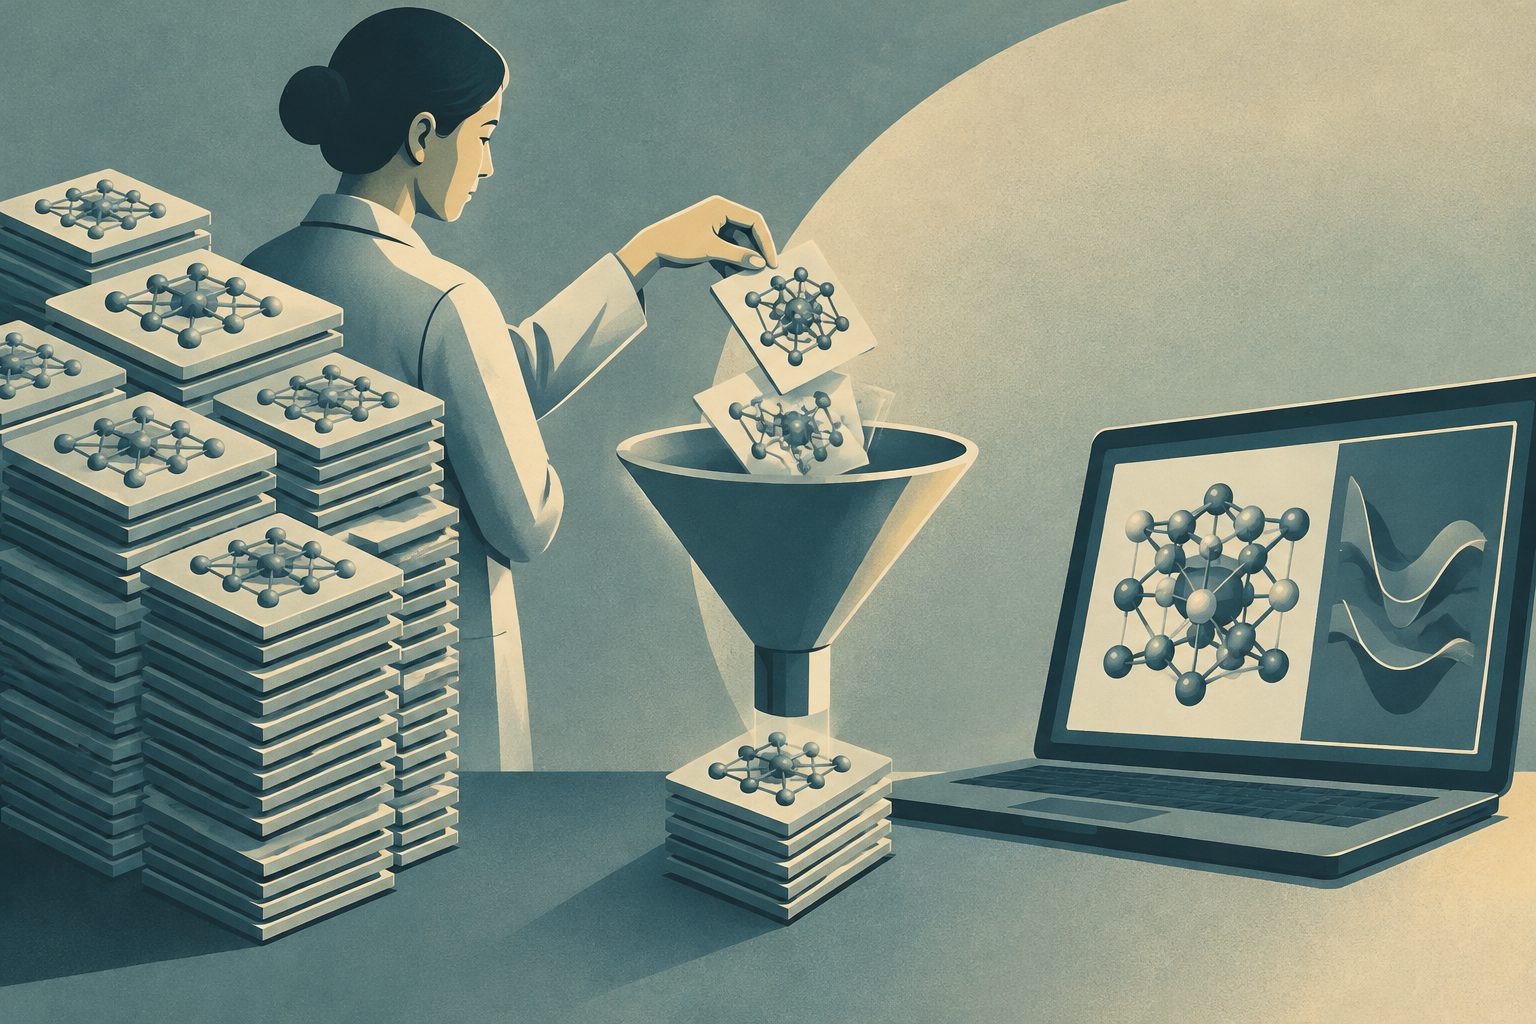
Machine-learning systems that predict the electronic properties of materials are often trained on large collections of results from computationally expensive calculations. The new study reports that these datasets contain substantial redundancy across diverse material systems, which the researchers link to the low intrinsic dimensionality of the underlying information.
Randomly removing data caused only small losses in predictive accuracy, while a method designed to sample examples across different levels of learning difficulty retained chemical accuracy and generalizability with up to 100 times less data. Training was also at least three times faster in the reported tests.
How much data was redundant
The researchers found significant overlap in electronic-structure datasets across diverse material systems. Even random pruning—removing data without selecting particular examples—could substantially shrink datasets with minimal degradation in predictive accuracy.
A coverage-based strategy that samples data across the full range of learning difficulties almost always preserved chemical accuracy and model generalizability while using up to two orders of magnitude less data. It also reduced training time by a factor of three or more.
The study further found that the essential electronic-structure information lies on a low-dimensional, nonlinear manifold—a space with fewer effective dimensions than the original data. The researchers say this may help explain why the data can be pruned so extensively. Their findings are consistent with the idea that nearby atomic environments strongly influence electronic properties.
Why smaller datasets matter
Generating electronic-structure data with Kohn-Sham density functional theory is computationally expensive. If smaller, representative datasets can support accurate predictions, researchers may be able to reduce the calculations, storage and training effort needed for some materials machine-learning applications.
The findings also point toward developing minimal datasets tailored to particular classes of materials, rather than assuming that very large datasets are always necessary. The abstract does not establish that the same reductions will apply equally to every material system or prediction task.
Evidence and caveats
The evidence comes from computational tests of dataset-pruning strategies and an analysis of the structure of electronic-structure data. The study reports results across diverse material systems, but the abstract does not give the number or types of systems, the prediction tasks, or the exact validation procedures.
The results support substantial data reduction in the tested settings, but they do not show that any dataset can be reduced by 100 times without loss. The abstract also does not specify how performance changed for each system or how well the findings extend beyond the tested materials and models.