A study finds that predicted traits can identify the right genome under favorable assumptions, but realistic conditions make reliable matching unlikely.
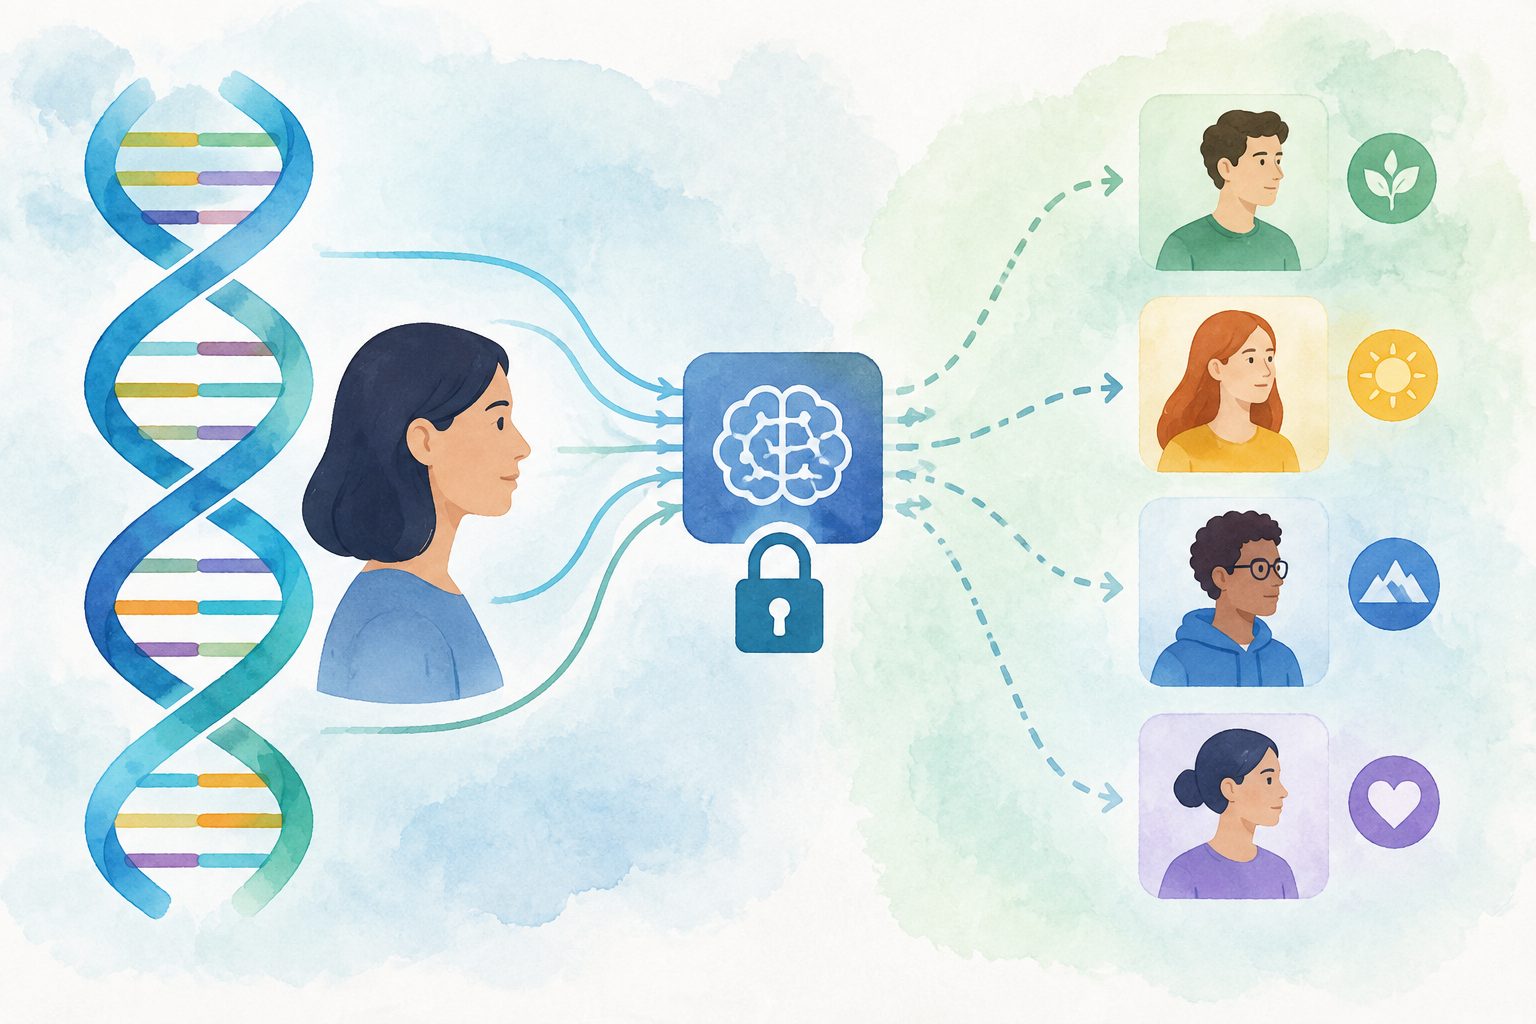
The researchers built a probabilistic framework that compares a person’s traits with genetic scores calculated from a genome. The framework accounts for how accurately traits can be predicted and for genetic and environmental links between traits. They benchmarked it against an existing tool and tested how the assumed chance of a true match affects results.
With a 50% prior chance that the genome and traits belonged to the same person, the method achieved more than 99% precision at 40% recall. But the researchers estimated that realistic priors are no higher than 4 × 10⁻⁴%, reducing precision to below 0.13% at the same recall. Attempts to identify carriers of the APOE-ε4 variant were also effective only at low recall.
What the matching test found
The researchers’ method, called PGMatch, compares observed traits with polygenic scores—genome-based estimates related to traits—to judge whether they came from the same person. It performed better than the comparison tool used as a benchmark.
The result depended strongly on the prior probability that a genome and a set of traits belonged to the same individual. At a 50% prior, PGMatch reached precision above 99% while recovering 40% of matching cases. Under the study’s estimate of realistic priors, no higher than 4 × 10⁻⁴%, precision was below 0.13% at the same recall.
The method was also tested for inferring APOE-ε4 carrier status. Precision above 50% was achieved only when recall was below 20%, meaning that most carriers would not be identified at that level of precision.
Why the risk still matters
Removing names and other direct identifiers from genome data does not eliminate every possible way of linking a genome to a person. This study evaluates one proposed route: comparing known traits with traits predicted from genetic data.
The findings suggest that this approach is technically possible but has limited practical value when the initial chance of a correct match is very small. They also indicate that the method is unlikely to reliably reveal APOE-ε4 carrier status under the conditions examined, although the risk depends on prediction accuracy, trait relationships and the prior probability of a match.
Evidence and caveats
The study presents a probabilistic framework and benchmarks its performance using modeled matching and mismatching genome–trait pairs. Its calculations incorporate the accuracy of genetic predictions and genetic and environmental correlations between traits. The researchers provide both a supervised approach, which uses individual-level data and represents an upper limit of performance, and an unsupervised approach that uses publicly available summary statistics and is intended to better reflect real-world conditions.
The reported precision changes substantially with the assumed prior probability of a match, so the results are estimates tied to those assumptions rather than a single universal risk level. The excerpts do not establish how the method performs across every population, trait set or data-sharing setting. The findings therefore describe the modeled and benchmarked effectiveness of this particular re-identification approach, not the success rate of all possible attacks on genome data.