A quantum-inspired design for reconfigurable hardware also reported up to 4.1-fold better energy efficiency than conventional comparison systems.
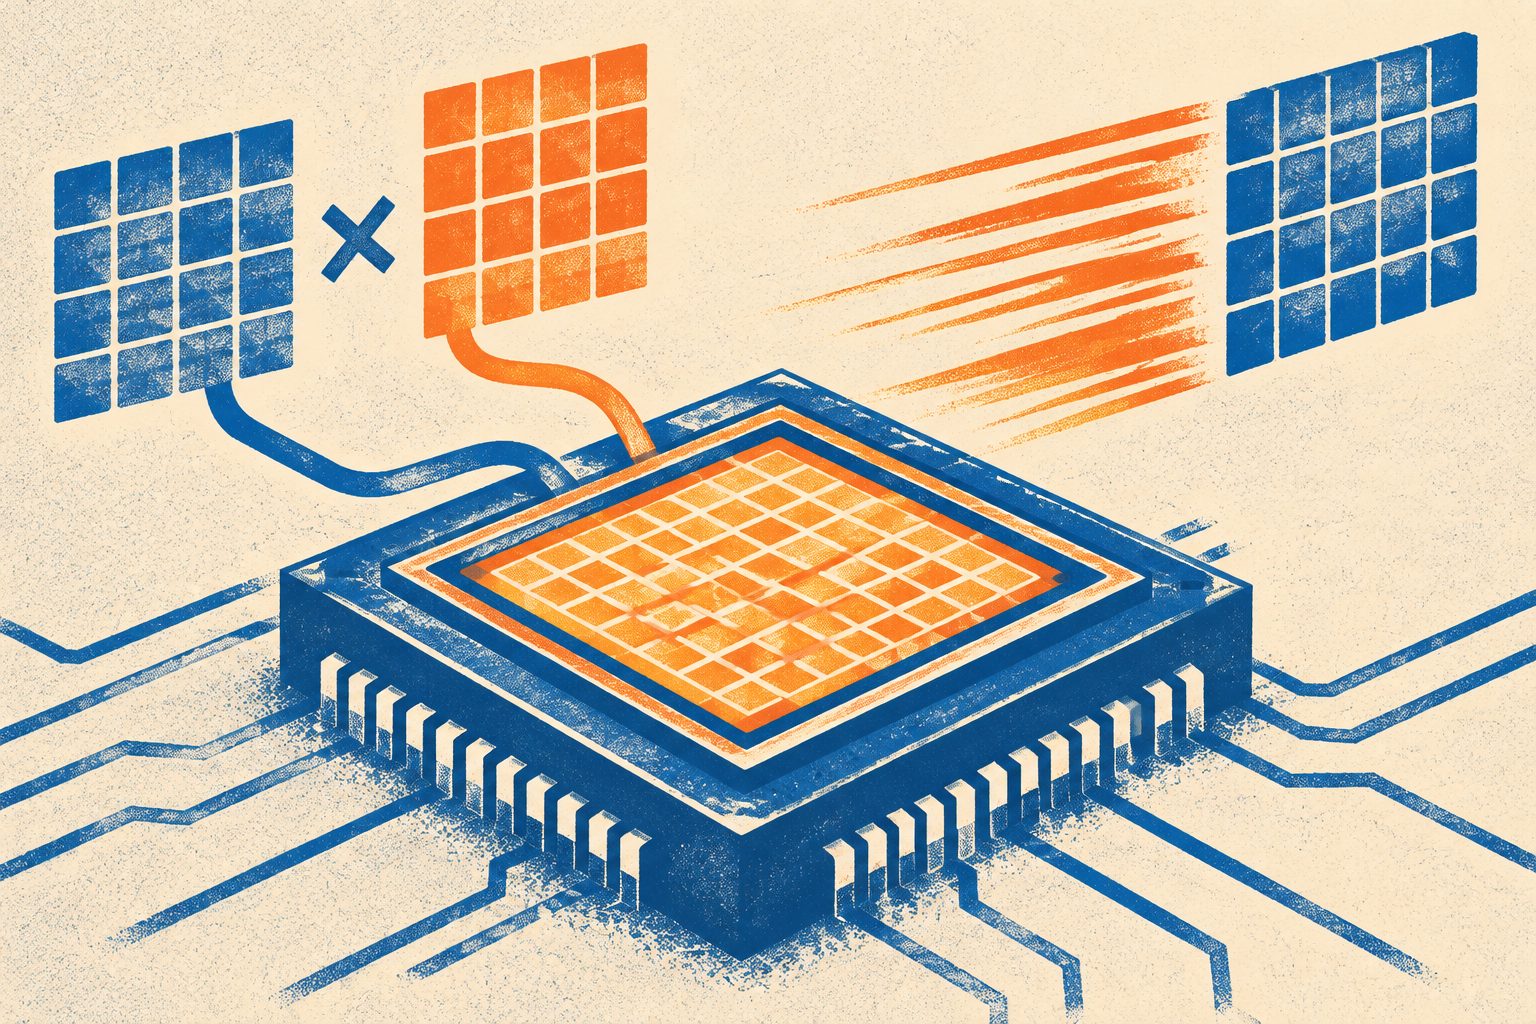
The Quantum-Inspired Matrix Engine, or QIME, is a classical hardware design built for field-programmable gate arrays, which are programmable chips. It uses parallel data paths, closely linked processing units and adjustable numerical precision to handle several parts of matrix calculations at once. The design can also reconfigure parts of its hardware for different matrix sizes and operations while running.
The researchers tested QIME on matrix multiplication, decomposition and convolution benchmarks. They report up to a 6.3-fold speedup and a 4.1-fold improvement in energy efficiency compared with conventional matrix co-processors and embedded graphics processors. The work is aimed at embedded systems where computing speed, power use and flexibility are important, including edge artificial intelligence, robotics and scientific sensing.
What the hardware achieved
QIME was evaluated using benchmarks for matrix multiplication, decomposition and convolution. Across representative operations, it provided up to 6.3 times the speed and up to 4.1 times the energy efficiency of the comparison systems described in the paper. A reported hardware comparison lists an 11.7-millisecond latency for a 128-by-128 matrix multiplication workload on QIME, compared with 15.2 milliseconds on a Jetson TX2 graphics processor and 74.3 milliseconds on an ARM Cortex-A53 processor. The same comparison lists QIME’s energy efficiency as 8.7 GFLOPS per watt, versus 6.4 for the Jetson TX2 and 2.1 for the ARM processor.
The design used parallel processing units that share intermediate results, hardware that can be partly reconfigured for a changing workload, and adjustable precision. Lower precision can improve performance and energy use when the workload allows some loss of numerical accuracy.
Evidence and caveats
The evidence comes from experimental benchmark tests of a QIME implementation on programmable hardware, compared with conventional processing platforms. The reported results cover representative matrix multiplication, decomposition and convolution operations rather than every possible workload. The design includes approximate computing, so some operating modes trade numerical precision for speed or energy efficiency. The excerpts do not provide enough detail to determine how the results vary across a wider range of matrix sizes, applications or accuracy requirements. The authors identify quantum-inspired error correction, support for sparse and structured matrices, and hardware-software co-design as areas for future work.
// Source
SCCTS Journal of Embedded Systems Design and Applications · 2026 · DOI: 10.31838/esa/03.02.06
Authors: Moti Ranjan Tandi, M. Sathish Kumar
Institutions: Kalinga University, Excelsior College