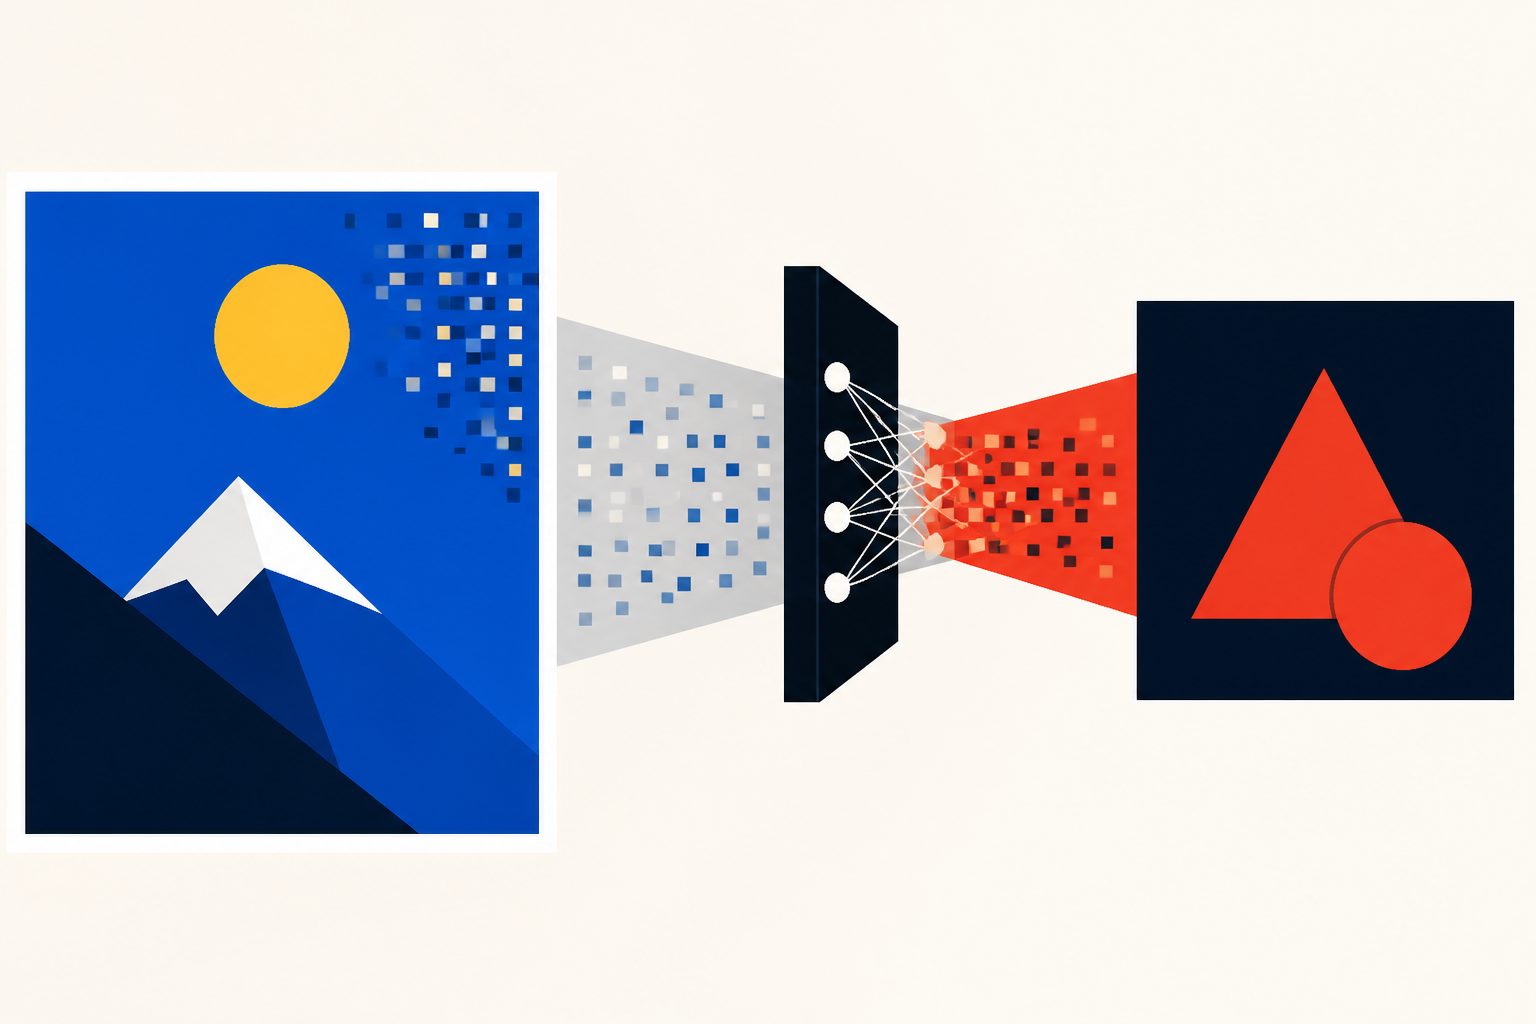
The study examines “goal hijacking via visual prompt injection,” in which an attacker places instructions inside an image. When a large vision-language model reads the image, those instructions may redirect it from its original task to a different one chosen by the attacker.
In tests described by the researchers, GPT-4V showed a 15.8% attack success rate. The analysis also found that success depended on the system’s ability to recognize characters in images and follow instructions.