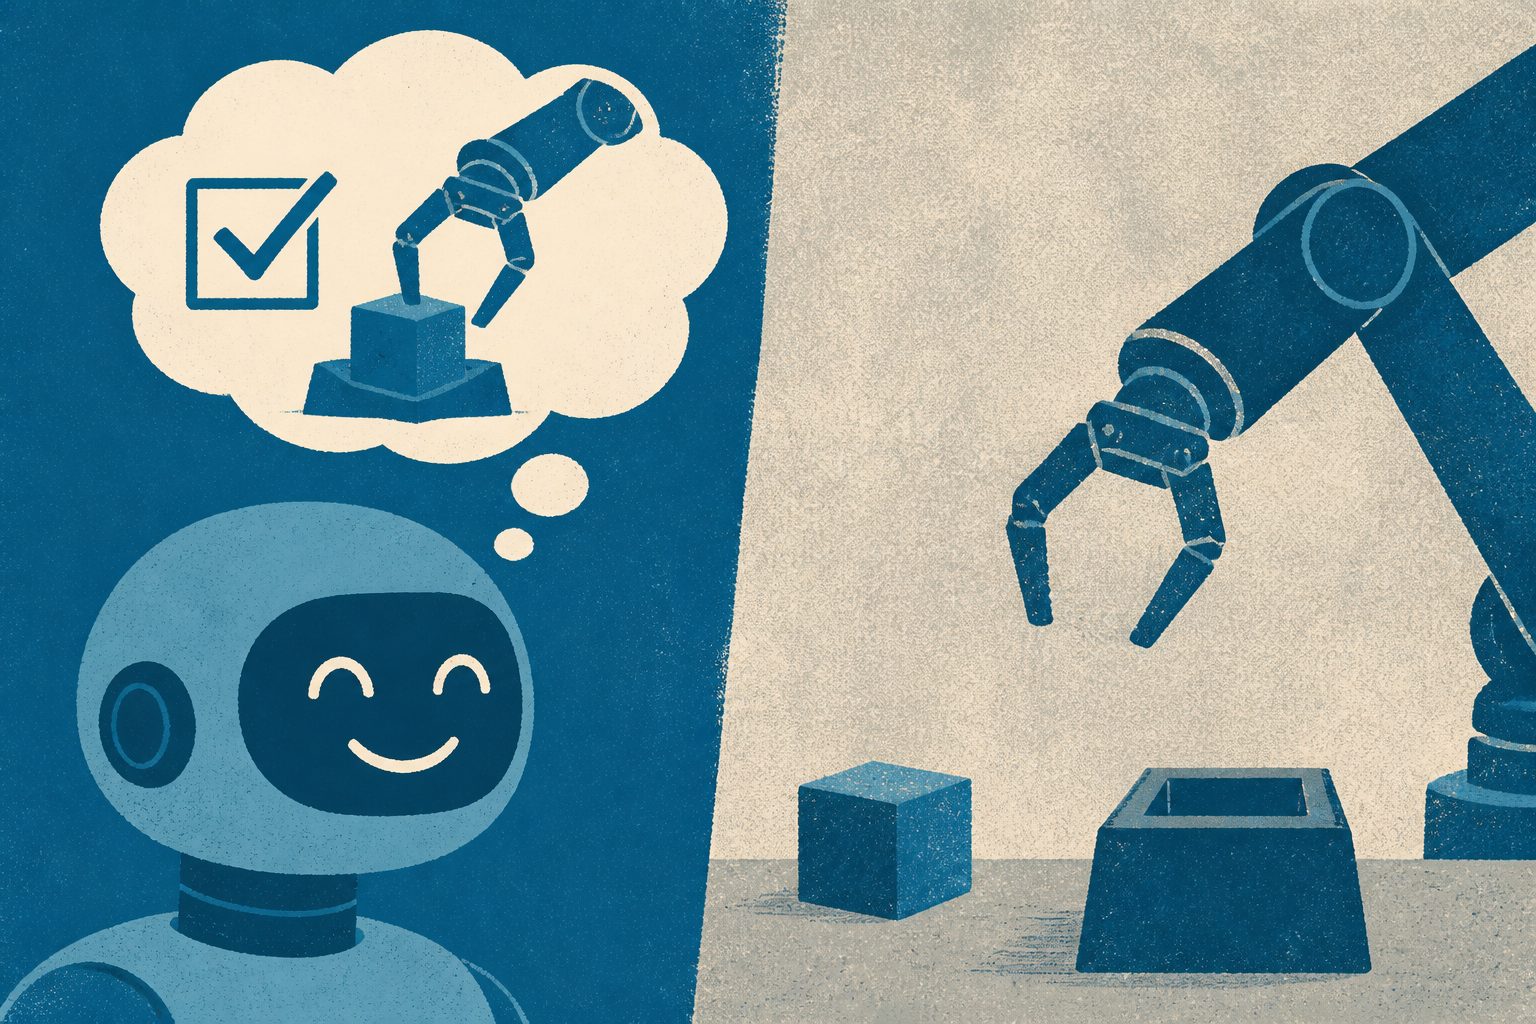
An exploratory analysis found repeated gaps between an AI system’s completed-sounding reply and the external action needed to finish a task.
The analysis separates three stages that can be mistaken for one another: producing a complete-sounding response, carrying out the required operation, and leaving evidence that the outside system actually changed. In the observed cases, the AI system had the knowledge and ability to perform the omitted action, and it could later do so after a minimal user follow-up.
The same workflow also included cases where the system completed external actions without prompting. The researchers therefore describe the failure as a repeated gap between what the system said was complete and what had actually changed, rather than as a simple lack of tool access.
When completion was only a message
Across repeated observed cases in a longitudinal, stateful AI workflow, the system produced a semantically complete terminal response while a required external action remained unexecuted and unevidenced. The omitted action could later be performed, and a minimal user follow-up containing little or no new operational information was enough to reopen the action path and produce the missing external state change.
The researchers distinguish semantic completion, operational completion and an evidenced change in the outside system. Successful episodes in the same workflow showed that the AI system could also initiate and complete external actions without a user prompt. The analysis considers several possible explanations, including accepting a terminal response too early, weakly linking required actions to the definition of completion, and treating an intermediate artifact as the final product.
Why the gap matters
For AI systems used in workflows, a response that sounds complete may not mean that the required outside action has occurred. Distinguishing the reply from the actual state of the external system could help people assess whether a task is finished and could inform how such systems represent and verify completion.
The findings also show why tool availability alone may not explain these failures: the system had the relevant capability and sometimes used it successfully. The study does not identify which proposed explanation caused the observed gap.
Evidence and limits
This is an exploratory failure analysis based on repeated observations from one longitudinal, stateful AI workflow, with successful tool-use episodes used as contrast cases. It documents the sequence of responses, attempted or omitted actions and later recovery after a low-information user follow-up.
The abstract does not establish a causal mechanism, so it cannot determine why the system stopped before carrying out the external action. The observations also do not by themselves show how often this failure occurs in other systems or workflows.
// Source
Zenodo (CERN European Organization for Nuclear Research) · 2026 · DOI: 10.5281/zenodo.22309887
Authors: Alen Širola