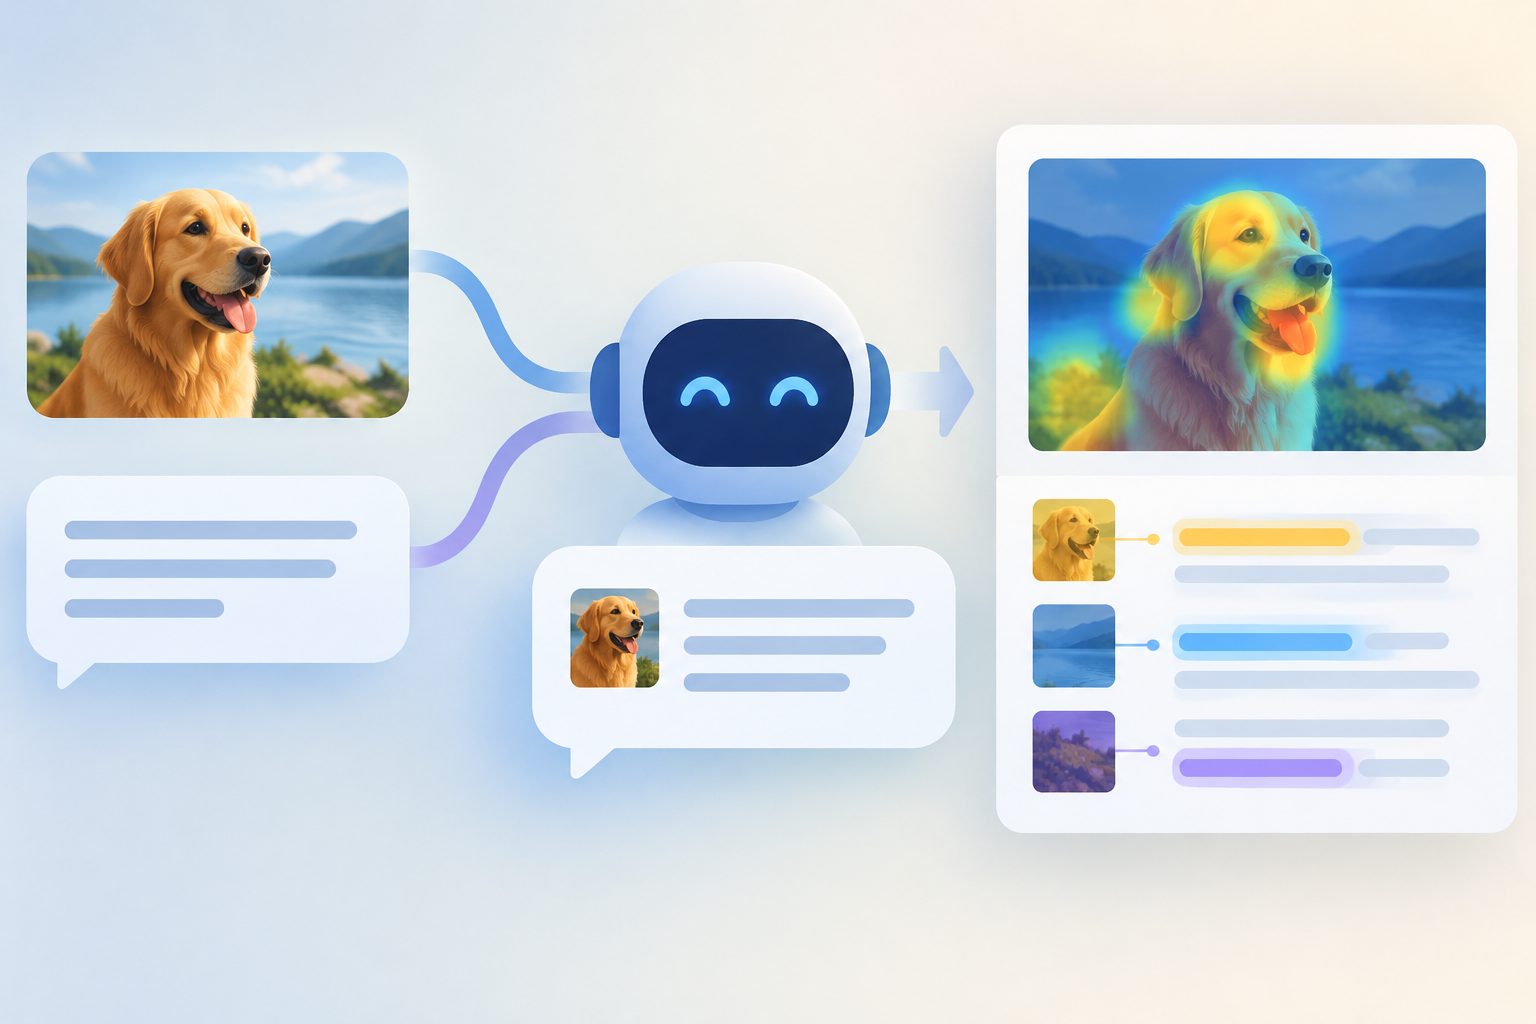
MultiSHAP estimates which image patches and text tokens work together or interfere when a multimodal AI makes a prediction.
MultiSHAP uses a mathematical approach called the Shapley Interaction Index to estimate pairwise effects between image patches and text tokens. It repeatedly masks combinations of visual and textual elements, then uses the model’s score to estimate whether the pair contributes more together than it would separately, or instead reduces the combined contribution.
The framework is designed to work without a model’s internal weights, gradients or attention data. It can produce explanations for an individual prediction as well as summaries of interaction patterns across a dataset, provided the model allows separate image and text perturbations and returns a suitable score.
How images and words interact
The analysis identified four types of image–text interaction: helpful synergy, in which visual and textual evidence supports a correct prediction; harmful synergy, in which irrelevant evidence is reinforced; helpful suppression, in which misleading cues are reduced; and harmful suppression, in which important evidence is down-weighted.
In visual question answering and image-text retrieval experiments, the researchers reported that these interaction patterns captured behaviorally relevant relationships. Pair-level evaluations provided partial evidence that the estimated links between image patches and text tokens contained information beyond single-modality saliency measures.
A rare-disease diagnosis analysis reported stronger cross-modal synergy for cohorts with more distinctive facial features. The mean synergy ratios were 0.61 for CdLS, 0.59 for Noonan syndrome and 0.54 for Angelman syndrome; the corresponding synergy dominance ratios were 0.57, 0.56 and 0.53. The researchers interpreted this pattern as suggesting that cross-modal interactions contributed more when facial features were more informative for the prediction task.
Why paired clues matter
Most explanations for multimodal AI show where a model attends or which inputs are important, but they do not directly show how a particular image region and word affect one another. MultiSHAP offers a way to inspect those paired effects, including cases in which the two inputs reinforce a useful clue or combine to support a misleading one.
Because it uses model queries rather than internal model information, the approach could also be applied to systems whose internal workings are not available. Its explanations may help researchers examine individual decisions and identify recurring interaction patterns, although the method does not by itself establish that an interaction reflects the model’s intended reasoning.
Evidence and limits
The evidence comes from experiments on multimodal benchmarks involving visual question answering and image-text retrieval, along with case studies and a rare-disease diagnosis analysis. For each dataset, the researchers randomly sampled 500 examples and averaged results over three random seeds. They estimated interaction scores with Monte Carlo sampling, using 128 permutations per sample in the reported experiments.
MultiSHAP is not fully independent of model access: it requires a query interface that supports separate masking or perturbation of visual and textual inputs and returns a task-relevant scalar score, either directly or from a ranked output. Its estimates are approximate because exact Shapley interaction calculations would require many model evaluations. The work was evaluated on vision-language models, so its usefulness for other combinations of modalities remains untested here. The pair-level results offer only partial evidence that the estimated correspondences add information beyond unimodal saliency.
// Source
npj Artificial Intelligence · 2026 · DOI: 10.1038/s44387-026-00164-5
Authors: Kai Wang
Institutions: University of Pennsylvania, Children's Hospital of Philadelphia